spencer_engel
Expert ⭐️
July 30, 2025
New Idea

Allow more flexibility in "Load to People" Action

Related products:CS Data Management & Integrations
  • July 30, 2025
  • 8 replies
  • 253 views

I’m running into all sorts of issues with our Company Person data because of Gainsight’s strictness re: the Load to People action. Any other standard or custom object you load to in Gainsight allows you to choose your identifiers at will, which is great because sometimes you need that flexibility.


However, with Load to People, you must first define your identifier in Administration > People, which is set to “email” as default and until fairly recently was the only identifier you could pick (yuck). Now that we can change the identifier though, I changed ours a few months back from email to External ID. However, I’m realizing that my predecessor did not even map External ID for some of our Company Person records, so I’m trying to go back and either backfill the External IDs or mark them for deletion, whichever is appropriate.


Instead of just being able to change my identifier to “Email” for this one rule, I must go to Administration > People and add “Email” to the match criteria. 
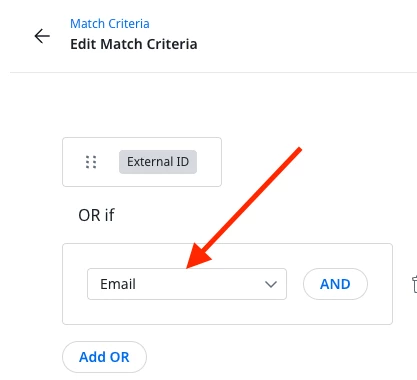


This is convoluted, but it’s ultimately ok because the rule does let me uncheck “External ID” as an identifier and only choose “Email,” which is necessary in this case because, again, the records I’m dealing with have no External ID and therefore that’s a useless identifier for my use case.


The real problem is that for some reason when I set this match criteria, it updates all my other Load to People rules and my SFDC connector job to include Email as a second identifier. Why?? 


So now I’m resorted to doing one of the following once I add Email as a second identifier for this cleanup process: 

  • Quickly go in to each Load to People rule and change all the identifiers back to just “External ID” and not Email, or 
  • Make sure I run this process during a time when none of my other Load to People jobs nor my SFDC connector job is running, then go back to Administration > People and undo “Email” as a second identifier.

This all seems so overly engineered. I understand this was probably designed to help sort of protect admins/ops professionals from themselves re: Contact/Person data, but in reality it’s quite restrictive and simply does not jive with how any other “load to object” action works, including, ironically “Load to SFDC Contact.”
 

8 replies

Shilpa Gumnur
Helper ⭐️
August 21, 2025

Hi ​@spencer_engel,

The identifiers in the People data model(Person, Company Person[CP], Relationship Person[RP]) have been centralised in the People Admin screen for the following reasons:-

1. Conjunction of 3 objects in one data model which is not the case for other objects. Data is loaded into Person and CP for most of the customers and for those with relationships, RP also comes into the picture.
2. The volume of data into People data model is larger in comparison to Company/Relationship objects and the volume matters because the system scans for dupes before ingesting a record.
3. Stay in tandem with sister products like Unification which helps in mass deduplication. To ensure the deduplication workflows established in Unification work seamlessly with any people data entered from other ingestion points, the identifiers used had to be common to prevent dupes from being either ingested or created with each runs of data loads.

Data load with a prevention of dupes check becomes difficult given the above scenarios if we have different identifier chosen for each rule with no centralised governance.

Let me forge a couple of examples

Rule 1 

Identifier: email

Sample data

Name: Jane Doe 

Email: jane.doe@abc.com

CustomID: Null

When this rule is ran, the system will check the people model database if any dupes exit in the Person object, if none found, it will insert the data.

Rule 2

Identifier: CustomID

Sample data

Name: Jane Doe

Email: jane.doe@abc.com

CustomID: 123

In this case, the system checks independently against CustomID if any record already exists and since it doesn’t find any, it will create a record for Jane Doe. Therefore we will end up having 2 records for Jane Doe.


The same scenarios when executed via the Match Criteria capability will ensure both the identifiers(if both identifiers are chosen at the ingestion points) are available for the system to check the existing records and if match is found for either of the identifiers, the system updates the record with the new value instead of creating a new record.


Match Criteria like you mentioned allows the admins to define specific criteria for specific rules of their choice. This was done to cater to requests from different admins who mentioned having data flowing from different sources and each source having a different identifier which they would like to use in data ingestion.

While solving for the multiple scenarios of Match Criteria being updated by the admins at any future point in time, we deliberated multiple options of applying the changes downstream to different rules/connectors and arrived at the current UX. 

Update scenario 1(Your case aligns with scenario 1)

When a single criteria exists and a new one is added, we went ahead with the rationale that:-

  1. Admins wouldn’t add a new one and keep the old one unless they want to include both the criteria in a fall through fashion.
  2. Data showed that Match criteria was not changed often, therefore when an admin chooses to do so, they would do it after analysing their current set up.
  3. We thought it is more helpful to include the new identifier by default(in this scenario, i’ll explain other scenarios below) to ensure the next data loads are subjected to the new checks and more dupes are avoided.

Update scenario 2.a

When multiple match criteria exist in the People admin but at the different ingestion points(rules, connectors) the admin had made certain preference and enabled only a subset of the criteria, then, the system will not include the newly added criteria by default to maintain the preferential selection made by the admin. In such cases, the admins will have to enable the newly added criteria for the rules/connectors of their choice. 

Update scenario 2.b

This is similar to scenario 1, When multiple match criteria exist in the People admin and the admin has allowed all the criteria in the ingestion points. Then the newly added criteria will by default be included in the list of criteria. 

People data model is architected differently from the Company and relationship objects to cater to different use cases of contact data. It is also the only core data entity that can be created/updated by the end users(they can create/edit person records if allowed by the admins). It also has to tackle the dupes prevention more rigorously than other areas given the volume and complex use cases, therefore the identifiers to be used have a different user journey. 

We will nonetheless explore if any more efficiencies can be brought in. 

Thanks,

Shilpa

spencer_engel
Expert ⭐️
August 21, 2025

@Shilpa Gumnur I appreciate the detailed and thoughtful response. As always, I wish your team would’ve consulted admins during this process because we would’ve definitely pushed back on the assumptions you all made. As I laid out in my original post, there is no efficient way whatsoever to (a.) switch identifiers and (b.) backfill data once you do switch identifiers. Because email was the only identifier accepted for such a long time, there are surely many orgs dealing with this issue where they changed their identifier (likely to SFDC contact ID) once Gainsight finally allowed identifiers other than email for Person/CP/RP data. 


Along those same lines of leaning on your admins, I can appreciate the concept of wanting to prevent a bunch of duplicate Person records and more or less “protecting customers from themselves.” But, again, you would’ve been well-served to consult the admin community here. A lot of us are quite experienced and can competently handle the complexities of getting identifiers right when it comes to dealing with Person data. Instead, we’re all stuck with this cookie-cutter solution that is not intuitive at all for less experienced admins and is overly restrictive and frustrating for more experienced admins - i.e. it doesn’t seem to hit the mark for anyone.

darkknight
Expert ⭐️
October 15, 2025

“wish your team would’ve consulted admins during this process”

Could be applied to almost everywhere in the system.

Jeff Kirkpatrick
andybuchanan
Contributor ⭐️⭐️⭐️⭐️
October 15, 2025

A simple use case is when you want to make a simple update to Person, Company Person or Relationship Person field on an existing record.  Instead of simply providing the actual unique identifier, which is the Person GSID, Company Person GSID, or the Relationship Person GSID - you must use the convoluted mapping process that can be prone to errors.

Bottom line is if I’m passing in the system generated ID for a given object, I think it’s more than reasonable that for an “Update” action I should be able to use that as the unique identifier and be done with it.  If I’m updating just the Company Person record, I don’t want to provide an identifier for the other objects as that can only create potential failures or issues if the lookups are setup incorrectly - I should not be asked to fill out details about the Person ID.  Similarly, if updating Relationship Person record I should not be required to touch the Person AND Company Person objects to do a simple update.

Andy
heather_hansen
VIP ⭐️⭐️⭐️⭐️⭐️
October 15, 2025

Agree with all of this.  Every other object that you want to update uses the GSID, so I don’t understand why People couldn’t be the same.  If necessary, seems like you could spin up a different path for Update versus Create similar to the CTA actions.

spencer_engel
Expert ⭐️
March 10, 2026

I’m bumping up against this issue again due to PX data. We have PX setup in one of our products, and it creates a Person record in Gainsight if PX sees a matching Company ID and Person email. Great. The problem is, in order to get our Adoption Explorer dashboard working correctly, we also need to load the “PX Identify ID” to the Person record. However, almost all of these PX-generated contacts don’t have a contact ID in Salesforce, and because Gainsight makes it so difficult to simply change our identifiers in the Load to People action, support is telling us our best option is to temporarily change our identifier to email in order to backfill this PX Identifier ID.


Unlike my original scenario that spawned this post, the PX Identify ID load is an ongoing process that needs to happen, not just a one-time thing. So if the answer is that we as admins would be expected to change our Person identifier to email once a week (or however often) in order to load these PX Identify IDs, that’s not realistic.

Expert ⭐️
August 6, 2026

Bumping this on up.


We for some reason had dupes loaded into our Company person object. What should be an easy clean up rule by minimizing the created date and selecting that GSID to keep and use to mark records to keep is impossible due to this limitation.


Seems like there should be an override somewhere for this. Or like it was done with load to relationship and upsert vs update, email and company id are required fields unless you source the actual gsid from those objects. Like with Relationship if it is an update you only need the gsid of the relationship vs an upsert you need name, type id, company, etc.

darkknight
Expert ⭐️
September 14, 2026

Related:  


Salesforce Flows function as an open database orchestration engine; Gainsight should do the same. It’s so maddening that we have these limits in place that make our jobs harder than they need to be.

FYI ​@rakesh 

Jeff Kirkpatrick